Do I Need a Reranker for RAG? Semantic Search vs. Reranking
Test a reranker when relevant documents rank too low. Fix missing candidates first, then measure answer quality, latency, and cost.
Not always. Test a reranker for RAG when relevant documents reach the candidate set but rank below the passages selected for generation. If the answer-bearing document never reaches the candidate set, fix retrieval first: a reranker can reorder supplied text, not recover missing evidence. Keep the extra stage only when measured answer quality justifies its latency and cost.
Semantic search and reranking solve different problems. Here, semantic search means first-stage candidate retrieval by meaning; in broader usage, the term can include the whole relevance pipeline. The useful boundaries are:
- Retrieval finds candidates in a large collection.
- Rank fusion combines candidate lists produced by different retrieval methods.
- Reranking improves the order of candidates already found.
Before choosing a model, inspect the candidate list: is the right document missing, or merely too low in the results? This is one reason a vector database alone does not make a RAG system.
What should I fix when semantic search misses the answer?
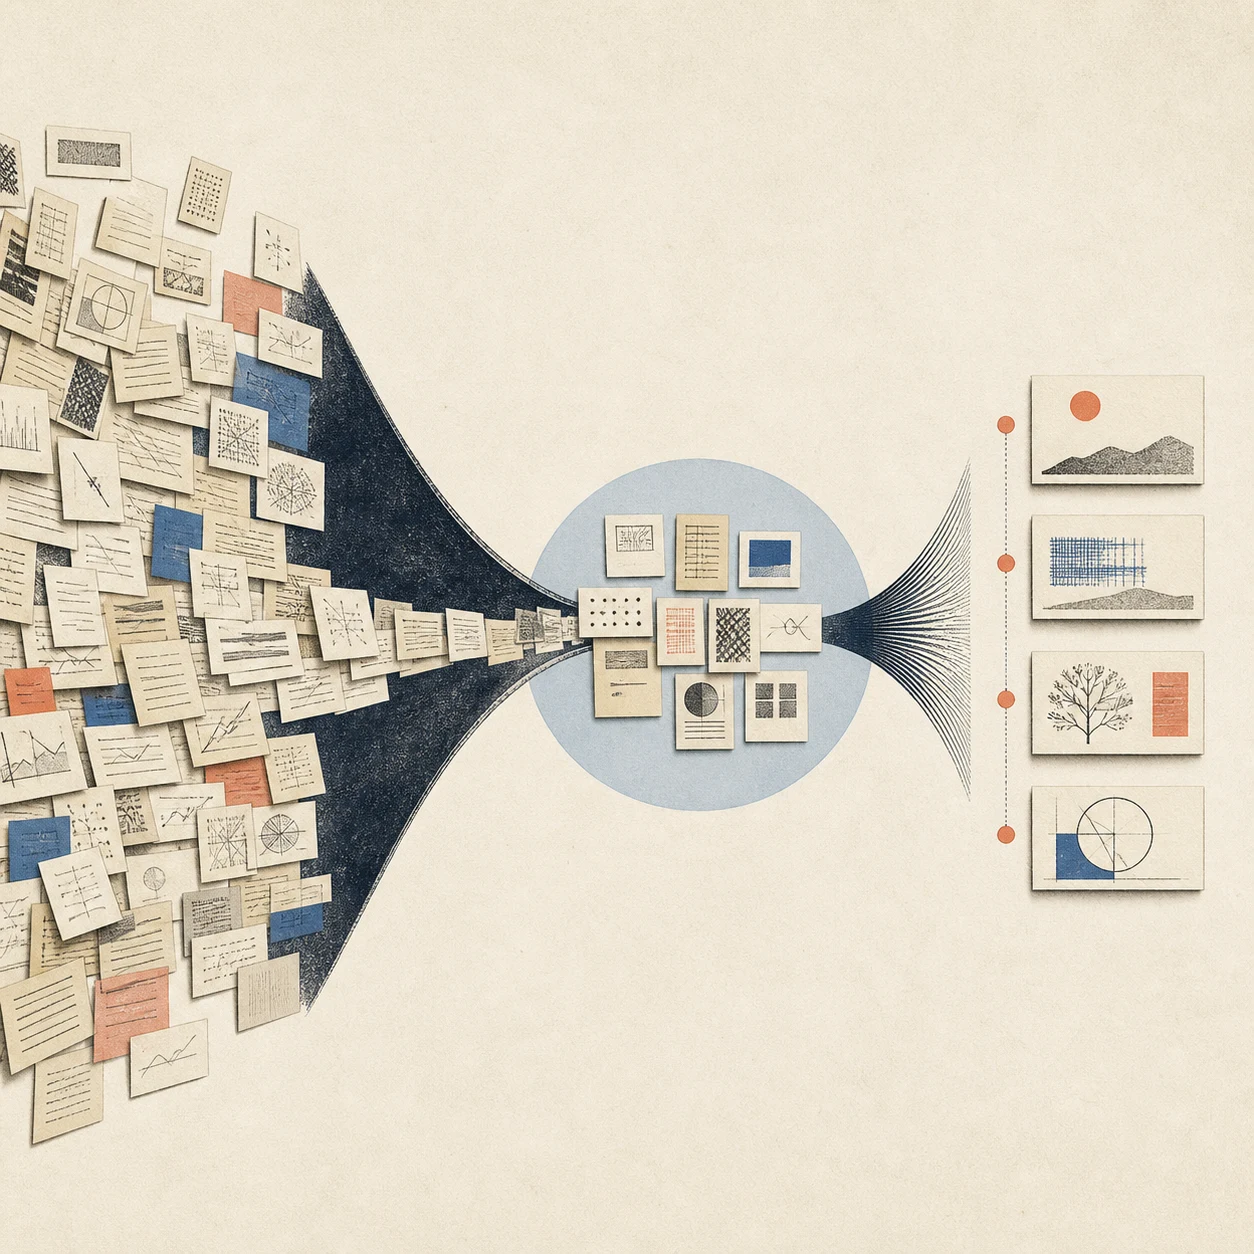
A retriever reduces a large corpus to a candidate set that a more expensive stage can inspect. If a knowledge base contains one million chunks, the retriever might select 50. Those 50 are now eligible for reranking; the other 999,950 are not.
When the correct document is missing, investigate the retrieval stage:
- Was the document indexed?
- Does the chunk make sense on its own?
- Does it contain the product code, policy name, or wording people search for?
- Is the query in a language the retrieval model handles well?
- Did a score threshold remove the document too early?
- Is the candidate limit too small?
- Would a lexical and semantic candidate union improve coverage?
Corpus preparation matters here. A header-only chunk, a policy split across pages, or important terms stored only in metadata can make the right source difficult to retrieve regardless of the reranker used later.
When should I use lexical, semantic, or hybrid retrieval?
There is no universally best way to build candidates. Each method preserves different evidence.
| Method | What it is good at | Typical blind spot |
|---|---|---|
| Lexical search | Exact terms, names, error messages, legal clauses, SKUs, and other identifiers | Paraphrases that share few words with the indexed text |
| Dense semantic search | Related meaning even when the query and document use different wording | Rare literals, fine details, negation, or several constraints compressed into one vector |
| Learned sparse retrieval | Term-based retrieval with learned weighting and possible term expansion | Index size and latency still depend on how sparse the representation really is |
| Hybrid retrieval | Coverage from complementary lexical and semantic candidate lists | Needs a clear way to merge scores or positions and remove duplicates |
Lexical retrieval is broader than BM25, but BM25 remains a useful reference point. It rewards term matches while accounting for term rarity, repeated occurrences, and document length. It is often a strong choice for exact identifiers, provided the index tokenizer preserves them.
Dense retrieval encodes queries and documents separately as vectors, then searches for nearby vectors. This makes large-scale search practical because document vectors can be prepared ahead of time. The Dense Passage Retrieval paper demonstrated the value of this design for open-domain question answering, but its results do not mean dense retrieval always beats BM25 in every domain.
Learned sparse models such as SPLADE keep a term-oriented, sparse representation while learning weights and expansions. They belong in the candidate-generation conversation; “sparse” does not automatically mean “classical” or “cheap.”
Hybrid retrieval combines methods. The important detail is where the combination happens. If lexical scoring is applied only after semantic search has already discarded a document, it cannot recover that document. To improve candidate coverage, form a union of candidates from the retrieval methods before cutting the list down.
Should I use RRF or a reranker?
Reciprocal Rank Fusion (RRF) is a simple way to combine ranked lists. It rewards documents that appear near the top of one or more lists. Because it works with positions, it avoids directly comparing a BM25 score with a cosine-similarity score—two numbers that do not share a meaningful scale.
That makes RRF useful when lexical and semantic retrieval produce complementary lists. It is inexpensive and requires no training. The original RRF paper reported strong results in its evaluated ranking experiments.
RRF still does not inspect what a document says. It cannot decide that one policy better satisfies a subtle condition, and it cannot apply a preference that was never represented by the input rankings. It is rank fusion, not semantic judgment.
- Use hybrid retrieval and RRF when different retrievers find different useful candidates.
- Use a reranker when the candidates are present but their final order needs a more detailed relevance decision.
How do I tell a retrieval failure from a ranking failure?
Consider this query:
How can I cancel an annual plan without paying a fee?
Assume the corpus contains these chunks:
- A — Monthly cancellation: Monthly plans can be cancelled at any time.
- B — Annual cooling-off period: Annual plans can be cancelled without a fee within 14 days of purchase.
- C — Annual cancellation: Annual plans may be cancelled after the first year with 30 days' notice.
- D — Refund timing: Approved refunds are returned within five business days.
- E — Enterprise contracts: Enterprise cancellation terms are defined in the signed agreement.
The following scores are invented diagnostic data, not measurements from AIVAX or any model. Their purpose is to keep the retrieval and reranking outputs visibly separate.
Failure 1: the right candidate is present but badly ordered
| Document | Retrieval rank | Retrieval score | Reranker rank | Reranker score |
|---|---|---|---|---|
| A — Monthly cancellation | 1 | 0.84 | 3 | 0.39 |
| C — Annual cancellation | 2 | 0.81 | 2 | 0.74 |
| B — Annual cooling-off period | 3 | 0.78 | 1 | 0.96 |
| D — Refund timing | 4 | 0.66 | 4 | 0.18 |
The retriever found B, but placed it below two broader cancellation passages. A reranker that reads the query and each candidate together can recognize the combined constraints: annual, cancel, and without a fee. This is a ranking problem.
Do not compare 0.78 with 0.96 as if the reranker “added” relevance. The two stages produce scores with different meanings. Compare ranks within each stage and evaluate them against relevance labels.
Failure 2: the right candidate never arrives
Now suppose retrieval returns A, C, D, and E. B is absent.
The reranker may place C first, but it cannot create B or search for it elsewhere. Even a perfect reranker must choose among the candidates it receives. This is a retrieval problem: improve the query, chunk, index, threshold, candidate depth, or retrieval mix.
This contrast is worth turning into a permanent test fixture. Store the query, corpus, expected relevant documents, candidate list, retrieval scores, and reranker output separately. Then a change to chunking does not get confused with a change to ranking.
Which reranker fits the decision I need to make?
Once candidate coverage is healthy, choose a reranker for the relevance decisions your queries require.
Lexical reranking
A lexical reranker is useful when the candidate set is already semantically reasonable and literal evidence should break ties. Product codes, quoted phrases, names, acronyms, and term proximity are common examples. It is often fast and predictable, but it will not resolve a complex preference expressed through different wording.
Cross-encoder reranking
A cross-encoder reads a query and one document together before assigning a relevance score. This allows detailed interaction between their words, unlike a single precomputed document vector. Passage Re-ranking with BERT is an early, influential example.
The trade-off is repeated work: each query-document pair normally requires inference. Cross-encoders therefore fit a shortlist better than an entire corpus. Candidate depth becomes a direct latency and cost decision.
Late interaction
Late-interaction models encode queries and documents separately but retain token-level representations for a finer comparison later. ColBERT introduced this design as a middle ground: more detailed interaction than one vector per document, while still allowing document representations to be prepared ahead of time.
Late interaction can support retrieval as well as reranking. It should not be treated as merely a cheaper cross-encoder.
LLM and listwise reranking
An LLM reranker can compare several candidates and return an order, sometimes using a natural-language instruction. This can help when relevance includes preferences such as “prefer official documentation, exclude opinion pieces, and prioritize material updated after a policy change.” Long lists may require several windows or calls, and output IDs need validation: a model can omit, duplicate, or invent them.
Do not assume that any large language model follows ranking instructions well. FollowIR found that existing retrieval models often struggled with long-form instructions and showed that instruction-specific training improved results on its benchmark. The practical lesson is that training and evaluation matter—not just parameter count.
Some requirements should not be delegated to a reranker at all. Access control, tenant boundaries, exact date cutoffs, price order, inventory, and other structured facts belong in filters or deterministic sorting whenever possible.
How many candidates should I retrieve and rerank?
For an initial experiment, try this pipeline:
- Retrieve 50 candidates. Use lexical, semantic, learned sparse, or a hybrid union according to the corpus.
- Keep retrieval evidence. Preserve source IDs, ranks, scores, and the retrieval path that found each candidate.
- Remove duplicates and enforce permissions. Do this before spending reranker capacity.
- Rerank the 50 candidates. Use a model appropriate for the language, document length, and decision complexity.
- Select the top 5 for generation. Pack only the useful text and source information the answer model needs.
- Evaluate the answer separately. A good ranking can still lead to a bad answer, and a correct answer can still be unsupported by its sources.
The numbers 50 and 5 are starting points, not universal defaults. A larger candidate set can improve the chance that a relevant document survives retrieval, but it also increases reranking work and can increase latency, token usage, and cost. A larger final context can include more evidence, but it may also add distraction.
How do I use reranking with AIVAX?
For semantic search over indexed collections, use POST /api/v1/query with collections and terms. AIVAX applies Reflex by default after candidate retrieval. Select another model with reranker, or set reranker: "none" to disable that stage. Filter-only requests without search terms bypass semantic search and reranking.
The collection request's top is the final result limit, not a separately configurable retrieve-50/rerank-5 pair. Its minScore can exclude candidates before reranking. A cutoff that removes the relevant document cannot be repaired by changing the reranker. AIVAX's rrf option combines semantic and lexical ranks within the retrieved pool; it does not add an independent corpus-wide keyword search.
For text your application already owns, use the standalone reranking endpoint. It accepts candidate strings without a collection. Available choices include Reflex, Cohere, Qwen, Jina, NVIDIA, and lexical reranking; they are not all the same architecture. Consult GET /api/v1/information/rerankers-models.json for current IDs, technical limits, and pricing rather than assuming every model accepts the same input size. RRF is collection-only.
To replay the cancellation example, send this JSON body to POST https://inference.aivax.net/api/v1/generations/rerank, with Content-Type: application/json and Authorization: Bearer YOUR_AIVAX_API_KEY from a trusted backend or local API client. You need an AIVAX account with available usage capacity; the call consumes reranking usage. Keep the key out of browser code.
{
  "model": "@aivax/reflex-v1",
  "query": "How can I cancel an annual plan without paying a fee?",
  "documents": [
    "Monthly plans can be cancelled at any time.",
    "Annual plans can be cancelled without a fee within 14 days of purchase.",
    "Annual plans may be cancelled after the first year with 30 days' notice.",
    "Approved refunds are returned within five business days."
  ],
  "top_n": 3,
  "min_score": 0
}
Read results[].index as the zero-based position in your input array. The answer-bearing passage is input index 1; check where it lands rather than expecting the illustrative scores above. Preserve the returned order. Reflex's public score and its lexical-calibrated ordering serve different purposes; the Reflex architecture guide explains that boundary.
Unlike collection minScore, standalone min_score filters reranker output. top_n then limits the response; lowering it does not mean the endpoint processes fewer input documents. Inspect usage.cost and consult current pricing before scaling the experiment.
How do I test whether reranking improves my RAG pipeline?
One end-to-end score is not enough to diagnose a pipeline. Measure the boundary between stages.
| Stage | Question | Useful measures |
|---|---|---|
| Retrieval | Did the candidate set contain the relevant documents? | Recall@k; hit rate@k |
| Reranking | Were useful candidates moved toward the top? | MRR; nDCG@k; Precision@k |
| Answer | Was the final response correct and supported? | Answer correctness; source support; human acceptance |
| Operations | Is the gain worth the added work? | Latency; cost; errors; throughput |
Recall@k asks what fraction of all known relevant documents appeared in the first k candidates. Hit rate@k asks whether at least one relevant document appeared. They can coincide when each query has one relevant answer, but they are not generally interchangeable.
MRR emphasizes the position of the first relevant result. nDCG@k rewards useful documents near the top and can represent graded relevance. Precision@k asks what share of the first k results is relevant.
For a retrieve-50, rerank-5 pipeline, measure:
- candidate recall or hit rate at 50 before reranking;
- MRR, nDCG@5, or Precision@5 after reranking;
- answer correctness and source support after generation;
- latency and cost for the complete task.
You can also measure reranking only on queries where a relevant document was present in the candidate set. That isolates ordering quality, but always report candidate recall beside it. Otherwise, a strong reranker score can hide a retriever that frequently misses the answer.
Use representative queries, relevance judgments, and real document shapes. Keep the corpus, chunking, candidate generator, candidate depth, and cutoff fixed when comparing rerankers. The BEIR benchmark is a useful reminder that methods behave differently across domains and that stronger ranking can carry substantial computational cost.
Diagnose first, then add complexity
Use this order when a search pipeline disappoints:
- The correct document is absent. Fix indexing, chunking, query formulation, thresholds, candidate depth, or retrieval coverage.
- Lexical and semantic retrievers find different useful documents. Combine their candidate lists; consider RRF when rank-based fusion is appropriate.
- The correct document is present but too low. Add or improve reranking.
- Literal evidence should decide among otherwise similar candidates. Try lexical reranking.
- The decision depends on nuanced semantic relevance. Test a neural reranker on labeled examples.
- The query includes detailed inclusion, exclusion, or preference rules. Test a model trained and evaluated for instruction following.
- The rule is structured and mandatory. Use a filter or deterministic sort, not a relevance model.
- Quality improves, but latency or cost does not justify it. Reduce candidate depth, batch work where supported, cache reusable representations, or remove the extra stage.
Also inspect duplicates, language coverage, document length limits, batch behavior, and cache boundaries before launch. These operational details can change both quality and cost, even when the ranking model itself stays the same.
Frequently asked questions
Can a reranker replace an embedding model?
Not in a large-corpus vector-search pipeline. The embedding model supports efficient candidate retrieval; the reranker orders those candidates for the query. If your application already has a small, bounded set of texts, you can send them directly to a standalone reranker without maintaining a vector index. That does not make reranking an efficient corpus-wide search method.
References
- Stephen Robertson and Hugo Zaragoza, The Probabilistic Relevance Framework: BM25 and Beyond.
- Vladimir Karpukhin et al., Dense Passage Retrieval for Open-Domain Question Answering.
- Thibault Formal, Benjamin Piwowarski, and Stéphane Clinchant, SPLADE: Sparse Lexical and Expansion Model for First Stage Ranking.
- Gordon Cormack, Charles Clarke, and Stefan Büttcher, Reciprocal Rank Fusion Outperforms Condorcet and Individual Rank Learning Methods.
- Rodrigo Nogueira and Kyunghyun Cho, Passage Re-ranking with BERT.
- Omar Khattab and Matei Zaharia, ColBERT: Efficient and Effective Passage Search via Contextualized Late Interaction over BERT.
- Yutao Sun et al., Is ChatGPT Good at Search? Investigating Large Language Models as Re-Ranking Agents.
- Orion Weller et al., FollowIR: Evaluating and Teaching Information Retrieval Models to Follow Instructions.
- NIST TREC, Common Evaluation Measures.
- Nandan Thakur et al., BEIR: A Heterogeneous Benchmark for Zero-shot Evaluation of Information Retrieval Models.